DevOps and Site Reliability Engineering in 2026: Complete Guide to CI/CD, Infrastructure as Code, Monitoring, Kubernetes, and Building Resilient Systems
DevOps and Site Reliability Engineering (SRE) have fundamentally transformed how software is built, deployed, and operated. In 2026, these practices are no longer optional — they are the baseline expectations for any engineering organization that wants to ship software reliably, rapidly, and at scale. The organizations that have mastered DevOps and SRE are shipping code multiple times per day, maintaining five-nines availability, and responding to incidents in minutes rather than hours. Those that haven't are being outcompeted by those that have.
This comprehensive guide covers everything you need to know about modern DevOps and SRE: the cultural foundations, the technical practices, the tools and platforms, and the organizational patterns that separate high-performing engineering organizations from the rest. Whether you're a developer trying to understand deployment pipelines, an operations engineer automating your infrastructure, an SRE building reliability into your systems, or an engineering leader designing your organization's DevOps journey, this guide provides the depth and breadth you need.
The DevOps Philosophy: Culture, Measurement, and Collaboration
DevOps is often misunderstood as a set of tools or a job title. It is fundamentally a cultural movement — a set of practices, values, and mindsets that break down the silos between development and operations teams to deliver software better, faster, and more reliably. The term was coined by Patrick Debois in 2009, and the movement was catalyzed by John Allspaw and Paul Hammond's landmark presentation "10+ Deploys Per Day: Dev and Ops Cooperation at Flickr" at Velocity Conference that same year.
The CALMS framework describes the core pillars of DevOps culture: Culture (fostering collaboration and shared ownership between dev and ops), Automation (eliminating manual, error-prone processes), Lean (applying lean manufacturing principles to software delivery — minimize waste, maximize flow), Measurement (tracking the right metrics to understand system and team performance), and Sharing (creating feedback loops and sharing knowledge across teams and organizations).
DORA Metrics: Measuring DevOps Performance
The DevOps Research and Assessment (DORA) team at Google has identified four key metrics that predict software delivery performance and organizational outcomes. These metrics are now the industry standard for measuring DevOps maturity:
Deployment Frequency: How often does your organization deploy code to production? Elite performers deploy multiple times per day. High performers deploy daily to weekly. Medium performers deploy weekly to monthly. Low performers deploy monthly to every six months. Deployment frequency is a leading indicator of DevOps maturity because high frequency forces automation and confidence in the deployment pipeline.
Lead Time for Changes: How long does it take to go from code committed to code running in production? Elite performers achieve this in less than one hour. This metric reflects the efficiency of the entire delivery pipeline — from developer workflow through testing, review, build, and deployment.
Change Failure Rate: What percentage of deployments cause a production failure requiring a hotfix, rollback, or patch? Elite performers see rates below 5%. High failure rates indicate insufficient testing or a lack of deployment confidence mechanisms.
Failed Deployment Recovery Time (MTTR): How long does it take to restore service after a production failure? Elite performers restore service in under one hour. This metric reflects the maturity of monitoring, incident response, and rollback capabilities.
Continuous Integration and Continuous Delivery (CI/CD)
CI/CD is the technical heart of DevOps — the automated pipeline that takes code from a developer's commit to production deployment. Understanding and implementing CI/CD well is the single highest-leverage technical investment an engineering team can make.
Continuous Integration
Continuous Integration (CI) is the practice of frequently integrating code changes into a shared repository, with each integration verified by an automated build and test sequence. The goal is to detect integration problems early, when they are cheapest to fix. Martin Fowler's original CI practices from 2006 remain as relevant today as when he wrote them: maintain a single source repository, automate the build, make the build self-testing, every commit triggers a build, fix broken builds immediately, keep the build fast, test in a clone of the production environment, make it easy to get the latest deliverables, everyone can see what's happening.
Modern CI systems (GitHub Actions, GitLab CI/CD, Jenkins, CircleCI, Buildkite, Tekton) execute a pipeline on every commit or pull request. A typical CI pipeline runs: static analysis (linting, security scanning, code style checking), unit tests, integration tests, build artifacts (Docker images, binaries, packages), publish artifacts to a registry, and report status back to the code review system.
GitHub Actions has become the dominant CI platform for open-source and cloud-native organizations. A GitHub Actions workflow is defined in YAML in the .github/workflows directory and can trigger on push, pull request, schedule, or manual dispatch. Actions from the GitHub Marketplace provide pre-built steps for common tasks. Composite actions allow packaging reusable CI logic. Reusable workflows enable organizations to share common pipelines across repositories.
Continuous Delivery and Deployment
Continuous Delivery (CD) extends CI to ensure the software is always in a releasable state — every commit that passes the CI pipeline can be deployed to production at any time. Continuous Deployment goes a step further: every commit that passes CI is automatically deployed to production without human intervention. The distinction matters: Continuous Delivery requires a manual approval step before production; Continuous Deployment does not.
The deployment pipeline is a sequence of stages, each providing greater confidence that the software is fit for production. A typical pipeline: commit stage (CI: build, unit test, static analysis) → acceptance stage (integration tests, performance tests, security scanning) → UAT/staging stage (exploratory testing, product sign-off) → production stage (deployment with traffic shifting and monitoring).
Deployment strategies control how new versions are rolled out to production. Blue-green deployments maintain two identical environments and switch traffic between them — zero downtime, instant rollback by switching back. Canary deployments route a small percentage of traffic to the new version, gradually increasing as confidence grows — catches issues before they affect all users. Rolling deployments update a subset of instances at a time — lower resource cost than blue-green but slower rollback. Feature flags (also called feature toggles) decouple deployment from release — code is deployed to production but features are disabled, then enabled incrementally or for specific users.

Infrastructure as Code (IaC)
Infrastructure as Code is the practice of managing and provisioning infrastructure through machine-readable configuration files rather than through manual processes or interactive configuration tools. IaC brings software engineering practices — version control, code review, testing, automation — to infrastructure management. When your infrastructure is code, it can be stored in Git, reviewed in pull requests, tested in pipelines, and deployed consistently across environments.
Terraform: The Dominant IaC Tool
HashiCorp Terraform is the most widely adopted IaC tool for cloud infrastructure. Terraform uses HCL (HashiCorp Configuration Language) to declare the desired state of infrastructure. The terraform plan command shows what changes will be made; terraform apply executes those changes. Terraform's state file tracks the actual state of provisioned infrastructure, enabling it to determine the diff between desired and actual state.
Terraform modules are reusable components that encapsulate infrastructure patterns. The Terraform Registry hosts thousands of community modules for AWS, GCP, Azure, and other providers. A well-structured Terraform codebase organizes infrastructure into environments (dev, staging, prod), with shared modules for common patterns (VPCs, EKS clusters, RDS instances). Remote state (stored in S3, GCS, or Terraform Cloud) enables collaboration and prevents state conflicts.
OpenTofu, the open-source fork of Terraform created after HashiCorp changed Terraform's license to BSL in 2023, has gained significant adoption by organizations wary of vendor lock-in. Pulumi offers an alternative to HCL-based IaC, allowing infrastructure to be written in Python, TypeScript, Go, and other general-purpose languages — enabling standard software engineering practices like loops, conditionals, and type safety in infrastructure code.
Configuration Management
While IaC tools like Terraform provision infrastructure, configuration management tools manage the software and configuration on those machines. Ansible is the most widely adopted configuration management tool, using YAML playbooks to describe the desired state of systems. Its agentless architecture (it connects via SSH) makes it easy to adopt. Ansible Tower / AWX provides a UI and API for managing Ansible at scale.
For containerized workloads, Helm is the dominant configuration management tool for Kubernetes. Helm charts package Kubernetes manifests with templating and values files, enabling reusable application deployments. Kustomize, bundled with kubectl, provides a simpler overlay-based approach to customizing Kubernetes manifests for different environments.
Containerization and Kubernetes
Containers have fundamentally changed how applications are packaged and deployed. A container packages an application with all its dependencies into a portable, isolated unit that runs consistently across environments. Docker popularized containers, and Kubernetes became the dominant orchestration platform for running containers at scale.
Docker and Container Best Practices
Effective Dockerization starts with well-crafted Dockerfiles. Best practices for production Dockerfiles: use official minimal base images (Alpine, distroless), use multi-stage builds to reduce final image size (build stage compiles, runtime stage contains only the binary), run containers as non-root users, pin dependency versions for reproducibility, layer Docker instructions to maximize cache reuse, scan images for vulnerabilities with tools like Trivy or Snyk.
A multi-stage build example: the first stage installs build dependencies and compiles the application; the second stage copies only the compiled binary from the first stage, producing an image potentially 10-50x smaller than a naive single-stage build. Smaller images have faster pull times, smaller attack surfaces, and lower storage costs.
Kubernetes Architecture and Core Concepts
Kubernetes (K8s) is a container orchestration system originally developed by Google and open-sourced in 2014. It automates deployment, scaling, and management of containerized applications. Kubernetes is declarative — you declare the desired state, and Kubernetes continuously works to maintain that state. The core architecture consists of: the control plane (API server, etcd, controller manager, scheduler) that manages the cluster state; and worker nodes (kubelet, kube-proxy, container runtime) that run application workloads.
The key abstractions in Kubernetes: Pod — the smallest deployable unit, containing one or more containers that share network and storage. Deployment — manages a replicated set of Pods, handling rolling updates and rollbacks. Service — provides stable network identity and load balancing for a set of Pods (ClusterIP, NodePort, LoadBalancer types). ConfigMap and Secret — inject configuration and sensitive data into Pods. PersistentVolume and PersistentVolumeClaim — manage durable storage for stateful workloads. Namespace — provides isolation between teams or environments within a cluster.
HorizontalPodAutoscaler (HPA) automatically scales the number of Pod replicas based on CPU utilization, memory utilization, or custom metrics. VerticalPodAutoscaler (VPA) automatically adjusts the resource requests and limits of Pod containers. Cluster Autoscaler adds or removes nodes from the cluster based on pending Pod resource requirements.
Kubernetes in Production
Running Kubernetes in production requires careful attention to several areas: resource management (setting appropriate requests and limits for all containers), network policies (controlling pod-to-pod communication), RBAC (role-based access control for cluster permissions), pod disruption budgets (ensuring service availability during node maintenance), and node affinity/anti-affinity (controlling pod placement for availability and performance).
Managed Kubernetes services (Amazon EKS, Google GKE, Azure AKS) handle the control plane, reducing operational burden. GKE Autopilot removes node management entirely — Google manages nodes, and you pay only for Pod resource usage. These services integrate natively with cloud-provider services: EKS with IAM, VPC, ALB; GKE with Cloud IAM, Cloud SQL, Cloud Load Balancing.
Service mesh technologies (Istio, Linkerd, Cilium) add a network layer to Kubernetes clusters that provides mutual TLS, traffic management, observability, and policy enforcement across services. Service meshes solve problems that application code should not have to solve: retry logic, circuit breaking, traffic splitting, and distributed tracing instrumentation.
GitOps: Declarative Operations
GitOps is an operational framework that applies DevOps best practices — version control, collaboration, compliance, CI/CD — to infrastructure automation. The core principle: Git is the single source of truth for the desired state of infrastructure and applications. Any change to production is made by modifying the desired state in Git; an operator (ArgoCD, Flux) watches Git and continuously reconciles the actual state to match the desired state.
ArgoCD is the most widely adopted GitOps operator for Kubernetes. It watches a Git repository containing Kubernetes manifests (or Helm charts, Kustomize overlays) and automatically applies changes when the repository is updated. ArgoCD provides a UI showing the sync status of all managed applications, with visual diff between desired and actual state. It supports progressive delivery through integration with Argo Rollouts for canary and blue-green deployments.
GitOps provides significant operational benefits: every change is audited in Git history; rollback is as simple as reverting a commit; the cluster state is always discoverable by examining the repository; and drift (manual changes to the cluster that diverge from Git) is detected and can be automatically corrected.
Site Reliability Engineering (SRE)
Site Reliability Engineering was invented at Google in 2003 by Ben Treynor Sloss to address the challenge of running large-scale production systems reliably. SRE applies software engineering principles to operations problems. The discipline is defined by its practitioners as "what happens when a software engineer is tasked with what used to be called operations." The Google SRE book, published in 2016, codified the practices and has become required reading for anyone building reliable distributed systems.
Service Level Objectives and Error Budgets
The foundational concept of SRE is the Service Level Objective (SLO). An SLO is a target value for a service level indicator (SLI) — a quantitative measure of service behavior. For example: an SLI might be "the proportion of HTTP requests that return a 2xx response code"; the corresponding SLO might be "99.9% of requests return a 2xx response code."
SLOs are more nuanced than traditional uptime commitments. They acknowledge that 100% availability is neither achievable nor desirable — the cost of the last 0.01% of availability is disproportionately high and the user experience difference between 99.99% and 100% is imperceptible. The right SLO reflects the reliability level that users actually need, not the maximum possible reliability.
Error budgets are the practical mechanism that makes SLOs actionable. If a service has a 99.9% availability SLO, it has an error budget of 0.1% — that is 43.8 minutes of downtime per month. The error budget can be "spent" on deployments (which risk introducing failures), planned maintenance, or absorbed as unexpected incidents. When the error budget is exhausted, the SRE and development teams must prioritize reliability work (incident investigation, fault tolerance improvements) over new features. This creates a natural feedback loop: teams that deploy carefully and build reliable systems have budget to ship new features; teams that introduce too many failures are forced to fix them.
Service Level Agreements (SLAs) are contracts with external customers that specify penalties for failing to meet commitments. The SLA target is always looser than the internal SLO, providing a buffer. If the SLO is 99.9%, the SLA might be 99.5% — the team has internal visibility into SLO breaches before they trigger SLA penalties.
Toil and Reducing It
Toil is manual, repetitive, automatable work of no enduring value that scales with service growth. Classic examples: manually scaling a fleet, responding to pages that always self-resolve, running the same deployment script every release, manually applying the same fix to multiple services. SRE teams target keeping toil below 50% of their time, using the remaining capacity for engineering work that permanently improves the reliability of systems.
Reducing toil is a form of continuous improvement. Every time an SRE manually performs a task, the correct response is to ask: "How could this be automated?" The first time may be manual; the second time should identify the automation; the third time the automation should be running. This philosophy, when consistently applied, compounds over time: systems become more self-managing, incidents become less frequent, and SREs spend more time on engineering that further reduces toil.
Observability: Logs, Metrics, and Traces
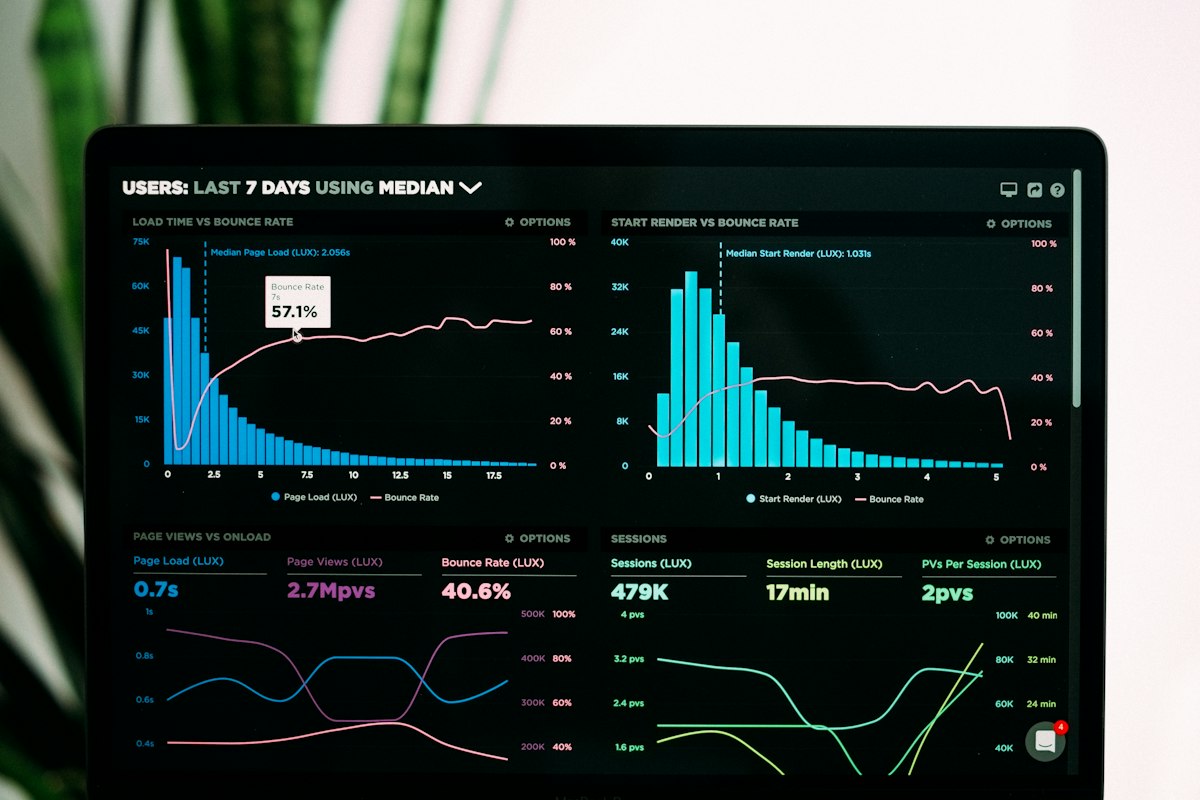
Observability is the ability to understand a system's internal state from its external outputs. A system is observable if you can answer questions about its behavior without having to modify it. The three pillars of observability — logs, metrics, and traces — provide complementary views into system behavior.
Metrics and Alerting
Metrics are numeric representations of data measured over time intervals. They are the foundation of operational monitoring: tracking CPU usage, memory consumption, request rates, error rates, and latency percentiles. Prometheus is the dominant open-source metrics system for cloud-native environments. It uses a pull model: Prometheus scrapes metrics from HTTP endpoints (/metrics) exposed by application services and infrastructure. The Prometheus data model is a multi-dimensional time series identified by metric name and key-value labels.
Grafana is the most popular visualization layer for Prometheus, providing rich dashboarding capabilities. Pre-built Grafana dashboards from the Grafana dashboard library cover common infrastructure components: Node Exporter (for host metrics), kube-state-metrics (Kubernetes cluster state), and application-specific dashboards. Grafana Alerting provides alert rule management with routing to notification channels (PagerDuty, Slack, email, OpsGenie).
Alerting philosophy: alert on symptoms that matter to users, not on causes. "Request error rate > 1% for 5 minutes" is a user-impacting symptom. "CPU usage > 80%" is a cause that may or may not lead to user impact. The distinction matters because cause-based alerts produce high volumes of noise that desensitize on-call engineers. Alert fatigue — when engineers stop responding urgently to alerts because most are non-urgent — is a serious reliability risk.
Distributed Tracing
Distributed tracing provides visibility into request flows across multiple services in a microservices architecture. A trace is a representation of a request as it flows through the system, composed of spans (individual units of work with start time, duration, and metadata). Tracing enables answering questions like "Why is this specific request slow?" and "Which service is causing the latency for this type of request?"
OpenTelemetry (OTel) has become the standard for distributed tracing instrumentation. It provides vendor-neutral SDKs for all major programming languages, enabling consistent trace context propagation. OTel data is exported to backends like Jaeger (open source), Zipkin (open source), Grafana Tempo, AWS X-Ray, Google Cloud Trace, or Honeycomb. The W3C Trace Context standard ensures trace context propagates correctly across service boundaries regardless of language or platform.
Structured Logging
Logs provide the granular event records that explain what happened and when. Structured logging — emitting logs as JSON objects with consistent fields — transforms logs from human-readable strings into machine-queryable data. A structured log event might include: timestamp, severity, service name, trace ID, user ID, request ID, the log message, and any relevant context fields. With structured logs, you can query across logs using standard tools.
The ELK Stack (Elasticsearch, Logstash/Fluentd, Kibana) and its successor the Elastic Observability platform remain popular for log management. Cloud-native alternatives include AWS CloudWatch Logs, Google Cloud Logging, and Azure Monitor. Grafana Loki, designed for Kubernetes environments, uses the same label-based query model as Prometheus, enabling correlation between metrics and logs in a unified Grafana environment.
Incident Management
Despite best efforts to build reliable systems, incidents — unexpected events that degrade service quality — are inevitable. Effective incident management is a critical SRE competency: the ability to quickly detect, respond to, and resolve incidents, then learn from them to prevent recurrence.
Incident response process: Detection (monitoring alerts, user reports, synthetic monitoring) → Triage (assess severity, who's impacted?) → Assign roles (Incident Commander coordinates response; Communications Lead updates stakeholders; Subject Matter Experts diagnose and fix) → Diagnose (find the root cause) → Mitigate (reduce impact, even if the fix is temporary — roll back, disable feature, shed load) → Resolve (permanent fix deployed and verified) → Review (write the post-mortem).
Blameless Post-Mortems
The blameless post-mortem is one of SRE's most important cultural contributions. A post-mortem is a written record of an incident: what happened, the impact, the timeline, the root cause, and the action items to prevent recurrence. "Blameless" means the focus is on systems and processes, not on finding the individual who "caused" the incident. The premise: failures are system failures, not individual failures. Engineers operate in complex systems with incomplete information and time pressure — when they make mistakes, the system allowed those mistakes to have outsized impact.
A good post-mortem includes: a clear impact statement (what broke, for how long, how many users affected), a timeline with precise timestamps, a root cause analysis (using techniques like 5 Whys or fault tree analysis), contributing factors beyond the immediate cause, and concrete action items with owners and deadlines. Post-mortems should be shared broadly within the organization — they are opportunities for organizational learning, not internal reports.
Security in DevOps: DevSecOps
DevSecOps integrates security practices into the DevOps pipeline, making security a shared responsibility throughout the software delivery lifecycle rather than a gate at the end. The "shift left" principle — catching security issues as early as possible in the development process, when they are cheapest to fix — is central to DevSecOps.
SAST (Static Application Security Testing): Analyze source code for security vulnerabilities without running the application. Tools: Semgrep, Bandit (Python), SonarQube, Snyk Code. Run in CI on every pull request. Fast feedback to developers on common vulnerability patterns.
DAST (Dynamic Application Security Testing): Test the running application by simulating attacks. Tools: OWASP ZAP, Burp Suite. Run in CI/CD against a test environment. Catches vulnerabilities that only manifest at runtime.
SCA (Software Composition Analysis): Scan dependencies for known vulnerabilities. Tools: Snyk, Dependabot, OWASP Dependency-Check. Maintains a software bill of materials (SBOM) and alerts when dependencies have published CVEs. Critical since the Log4Shell vulnerability demonstrated how a single widely-used library can affect thousands of applications.
Container security: Scan container images for OS and package vulnerabilities. Tools: Trivy, Grype, Anchore. Build container scanning into CI pipelines and block deployment of images with critical vulnerabilities. Use minimal base images (distroless, scratch) to reduce attack surface.
Infrastructure security: Scan IaC configurations for security misconfigurations before they reach production. Tools: Checkov, tfsec, KICS. Catch misconfigurations like public S3 buckets, overly permissive security groups, and missing encryption at the IaC definition stage.
Secrets management: Never store secrets in code or environment variables checked into source control. Use dedicated secrets management: HashiCorp Vault (cloud-agnostic), AWS Secrets Manager, Google Secret Manager, Azure Key Vault. Rotate secrets automatically. Scan repositories for accidentally committed secrets using tools like GitLeaks, truffleHog, or GitHub's built-in secret scanning.
Cloud-Native Architectures and Serverless
Cloud-native architecture designs applications specifically to exploit the capabilities of cloud platforms: elasticity, managed services, global distribution, and pay-per-use pricing. The CNCF (Cloud Native Computing Foundation) defines cloud-native as: containers, microservices, dynamic orchestration, and declarative APIs. The CNCF Landscape catalogs over 1,200 cloud-native tools and platforms — understanding which tools solve which problems is itself a significant challenge.
Serverless computing abstracts away all infrastructure management — you write and deploy functions, and the cloud provider handles provisioning, scaling, and availability. AWS Lambda (and equivalents: Google Cloud Functions, Azure Functions) enables event-driven architectures where functions are triggered by events (HTTP requests, queue messages, database changes, scheduled triggers) and scale to zero when idle. Serverless is ideal for variable or unpredictable workloads, event processing pipelines, and batch processing.
AWS Lambda cold starts — the latency added when a new function instance is initialized — have been dramatically reduced through provisioned concurrency, SnapStart (for JVM functions), and Graviton-based compute. For latency-sensitive functions, SnapStart reduces cold start latency by over 90% by taking a snapshot of a warm function execution environment.
Platform Engineering
Platform engineering is the discipline of building internal developer platforms (IDPs) that abstract infrastructure complexity and enable developers to self-serve the infrastructure and operational capabilities they need. Rather than every development team re-implementing the same DevOps patterns, a platform engineering team builds the paved road: standardized CI/CD pipelines, observability stacks, deployment abstractions, and self-service environments.
The Internal Developer Platform (IDP) typically provides: a self-service portal where developers can request environments, services, and resources; standardized CI/CD templates that implement security, testing, and deployment best practices; a service catalog documenting available services and their owners; and golden paths — recommended patterns for common use cases that teams can follow without deep infrastructure expertise.
Backstage, Spotify's open-source developer portal, has become the dominant platform for building IDPs. Backstage provides a plugin-based architecture for integrating the diverse set of tools in a modern engineering stack — GitHub, PagerDuty, Kubernetes, cost management, documentation — into a single developer-facing interface.
Cost Optimization in DevOps
Cloud costs are a significant and often poorly managed expense for organizations of all sizes. FinOps (Financial Operations) is the practice of bringing financial accountability to the variable spend model of cloud computing. In 2026, cloud cost management has become a core DevOps responsibility — the team that deploys the infrastructure should understand and be accountable for its cost.
Key cost optimization strategies: right-sizing (match instance types to actual workload requirements, using tools like AWS Compute Optimizer and GCP Recommender); reserved instances and committed use discounts (commit to usage in exchange for significant discounts on base workloads); Spot/Preemptible instances (use spare capacity at 60-90% discount for fault-tolerant workloads); auto-scaling (scale down during low-traffic periods); storage tiering (move infrequently accessed data to cheaper storage tiers); and eliminating waste (delete unused resources, orphaned EBS volumes, old snapshots, idle load balancers).
Kubernetes cost optimization is particularly complex because compute resources are shared across multiple workloads. Tools like Kubecost, OpenCost, and cloud-provider cost tools (AWS Cost Explorer with EKS views, GCP GKE Cost Allocation) provide per-namespace, per-workload cost visibility. Techniques like bin packing (scheduling Pods to maximize node utilization), using smaller node types for predictable workloads, and vertical pod autoscaling significantly reduce Kubernetes cluster costs.
DevOps Toolchain Overview
The modern DevOps toolchain is vast and continues to evolve. Understanding the categories and leading tools helps teams make informed choices.
Source Control: GitHub (dominant for most organizations), GitLab (popular for self-hosted), Bitbucket (Atlassian ecosystem). Git workflows: trunk-based development (preferred for high-frequency delivery, single main branch), GitFlow (branching model with feature/release/hotfix branches), GitHub Flow (simplified, feature branches + PRs to main).
CI/CD Platforms: GitHub Actions (tightly integrated with GitHub, extensive marketplace), GitLab CI/CD (self-hosted option, integrated with GitLab), Jenkins (mature, self-hosted, plugin-heavy), CircleCI, Buildkite (self-hosted agents, great for performance), Tekton (Kubernetes-native, CNCF project), Argo Workflows (Kubernetes-native, integrates with ArgoCD).
Container Registries: Amazon ECR, Google Artifact Registry, Azure Container Registry, Docker Hub, GitHub Container Registry (GHCR). Use lifecycle policies to automatically delete old images, signed images (Cosign, Notary v2) to verify image provenance, and vulnerability scanning on push.
Kubernetes Distributions: Amazon EKS, Google GKE, Azure AKS (managed), Red Hat OpenShift (enterprise on-prem), k3s (lightweight for edge), kind (Kubernetes in Docker for local testing), minikube (local development).
Service Mesh: Istio (comprehensive, complex), Linkerd (lightweight, simple), Cilium (eBPF-based, high performance, Layer 3-7). Service meshes provide: mutual TLS, traffic management, circuit breaking, distributed tracing, and observability — without application code changes.
Observability Stack: Prometheus + Grafana (metrics and alerting), Grafana Loki (logs), Grafana Tempo (traces), OpenTelemetry (instrumentation standard). Managed alternatives: Datadog (comprehensive, expensive), New Relic, AWS CloudWatch, Google Cloud Operations Suite.
Incident Management: PagerDuty (on-call scheduling, escalation policies), OpsGenie (similar capabilities), Slack (communication hub for incident response), Rootly and Incident.io (Slack-native incident management platforms with automated workflows).
Secret Management: HashiCorp Vault (cloud-agnostic, feature-rich), AWS Secrets Manager, Google Secret Manager, Azure Key Vault. In Kubernetes: External Secrets Operator syncs secrets from external providers into Kubernetes Secrets.
Building a DevOps Culture
DevOps transformations fail more often from cultural friction than from technical challenges. The technical tools are well-understood; the organizational change is hard. Key success factors for DevOps cultural transformation:
Shared ownership: Developers and operations teams jointly own the reliability and operability of systems. "You build it, you run it" — developers who carry the pager for their services make different architectural decisions than those who hand off to operations. The cultural shift from "we're responsible for what we ship" to "we're responsible for how it runs" is fundamental.
Psychological safety: Engineers must feel safe to report problems, experiment, and fail. Blameless culture — focusing on systems rather than individuals when things go wrong — is the foundation of psychological safety in engineering organizations. Amy Edmondson's research on psychological safety in healthcare teams maps directly to engineering organizations: teams with higher psychological safety take more risks, learn from failures faster, and perform better.
Leadership support: DevOps transformation requires executive sponsorship. Technical teams cannot change organizational structure, incentive systems, or budget allocation without leadership support. Leaders must explicitly prioritize reliability (not just features), invest in reducing toil, and accept that the first phase of a DevOps transformation may slow feature delivery as teams build the foundation.
Measurement and transparency: Make DORA metrics visible to the whole organization. Post-mortems should be public. On-call burden should be measured and managed. Cost attribution should be clear. Transparency creates accountability and enables improvement — you can't improve what you don't measure.
Chaos Engineering
Chaos engineering is the discipline of experimenting on a system in production to build confidence in its ability to withstand turbulent conditions. Netflix's Chaos Monkey, which randomly terminates production instances to ensure services can handle instance failures, pioneered the practice. Chaos engineering has since evolved into a systematic discipline with its own principles and tools.
The Principles of Chaos Engineering (from Gremlin and Netflix): build a hypothesis around steady-state behavior, vary real-world events (instance failure, network latency, disk exhaustion, packet loss), run experiments in production (or staging for more cautious organizations), automate experiments to run continuously, minimize blast radius (start small, fail safely). The goal is to discover weaknesses before they manifest as incidents, in a controlled way rather than during an actual emergency.
Chaos engineering tools: Chaos Monkey and the Netflix Simian Army (AWS-specific), Gremlin (commercial, comprehensive), LitmusChaos (Kubernetes-native, CNCF project), Chaos Toolkit (open source), AWS Fault Injection Simulator (managed, integrates with AWS services). GameDays — structured chaos engineering exercises where teams deliberately inject failures and practice their incident response — are an effective way to build chaos engineering muscles and validate runbooks.
AI-Augmented DevOps
AI is transforming DevOps practices across the pipeline in 2026. GitHub Copilot and similar tools have become standard in development workflows, but AI's impact extends well beyond code completion.
Intelligent CI/CD: ML models predict test flakiness and skip or quarantine unreliable tests. Test selection models run only the tests likely to catch regressions in a given change — dramatically reducing CI pipeline runtime. Deployment safety models score the risk of a given deployment based on historical data — change size, author experience, time of day, recent incidents. High-risk deployments trigger additional approval steps; low-risk deployments deploy automatically.
AIOps for incident management: Correlation engines group related alerts into incidents, reducing alert noise. Root cause analysis tools use ML to suggest the most likely cause of incidents based on historical patterns. Anomaly detection identifies unusual patterns in metrics and logs before they cross alerting thresholds. Natural language interfaces allow on-call engineers to query observability systems in plain English.
AI-powered log analysis: Large language models can parse unstructured log data and summarize what happened during an incident, reducing the time spent on log archaeology. Tools like AWS re:Post, Opsgenie AI, and specialized AIOps platforms are maturing rapidly in this space.
Automated remediation: Runbook automation tools (PagerDuty Process Automation, Rundeck) execute predefined remediation steps automatically when specific alert conditions are met. AI is beginning to generate and execute novel remediation actions — identifying that a service is OOMing and automatically increasing its memory limits, for example — though human oversight remains essential for complex or irreversible actions.
The Future of DevOps: Trends for 2026 and Beyond
Platform engineering is consolidating DevOps toolchains: instead of every team assembling their own set of tools, platform teams build standardized capabilities that development teams consume. The Internal Developer Platform becomes the interface through which development teams interact with infrastructure — abstracting the complexity of Kubernetes, cloud providers, and observability stacks.
eBPF (extended Berkeley Packet Filter) is enabling a new generation of observability and security tools that instrument the Linux kernel without modifying application code or inserting agents. Cilium (eBPF-based networking and security), Pixie (instant observability via eBPF), and Falco (runtime security) exemplify this trend. eBPF provides visibility into system calls, network events, and application behavior at kernel level, enabling production debugging without redeployment.
WebAssembly (Wasm) is emerging as a portable execution format for edge computing and serverless workloads. WasmEdge and wasmtime enable running Wasm modules at the edge, in serverless environments, and even as Kubernetes workloads — with sub-millisecond cold starts and stronger isolation than containers. The CNCF has established a Wasm working group anticipating significant adoption in cloud-native contexts.
Supply chain security has become a top priority following high-profile incidents like the SolarWinds attack and the XZ Utils backdoor. SLSA (Supply chain Levels for Software Artifacts) is a framework for securing the software supply chain from source to build to distribution. SBOM (Software Bill of Materials) generation is increasingly required by government contracts and enterprise customers. Sigstore (Cosign, Fulcio, Rekor) provides a free, public infrastructure for signing and verifying software artifacts.
Conclusion
DevOps and SRE represent a fundamental rethinking of how software is built and operated. The technical practices — CI/CD, IaC, containerization, Kubernetes, GitOps, observability — provide the mechanisms. But the cultural transformation — shared ownership, blameless post-mortems, psychological safety, data-driven improvement — is what makes the mechanisms work. Organizations that have fully embraced both the technical and cultural dimensions of DevOps are deploying code tens or hundreds of times per day, maintaining exceptional reliability, and recovering from incidents in minutes.
The journey to DevOps maturity is not a destination but a continuous improvement process. Start where you are: measure your DORA metrics, identify the bottleneck in your delivery pipeline, and make it better. Every organization's DevOps journey is different, but the destination — reliable, frequent software delivery — is the same. The engineers who understand and apply these practices are among the most valuable in the industry, and the organizations that have mastered them have a durable competitive advantage that compounds over time.



Comments
Post a Comment